Quality at scale, with humans in the loop.First of its kind.
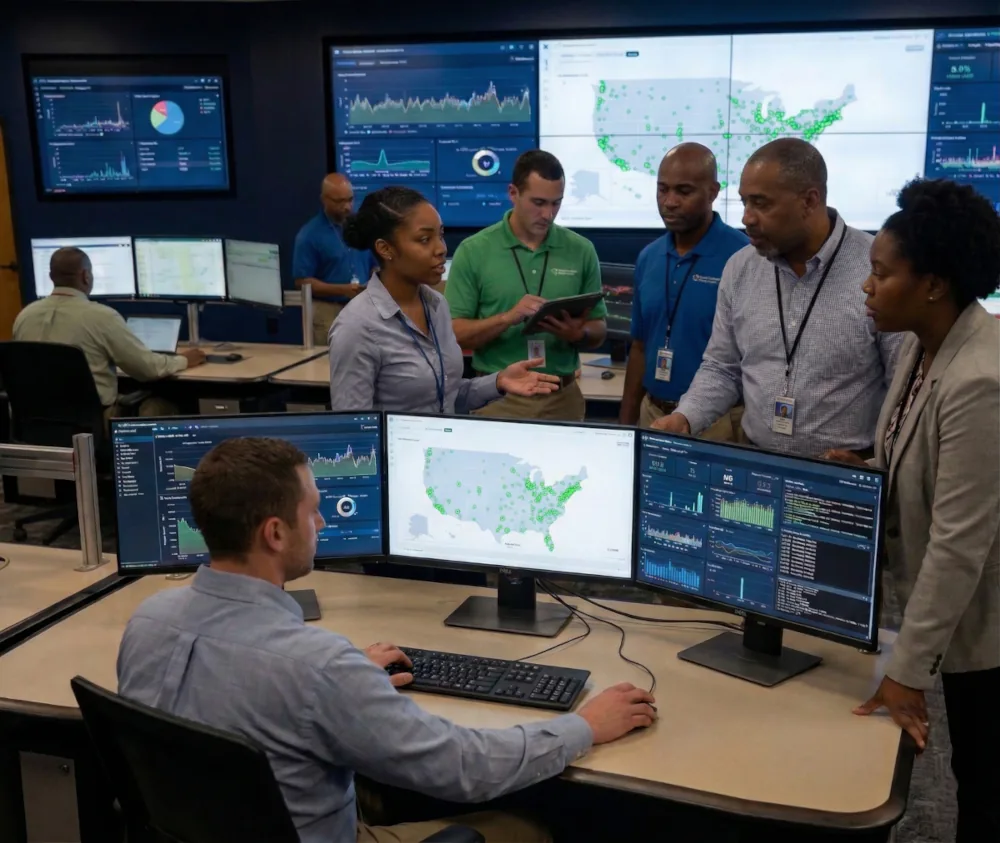
Our team in Bloomington, Indiana reviews translation quality and performance on every call, so you can rely on Kai for your most important conversations. Every conversation remains private.
The conversation stays private. No audio or transcripts.
Humans in the loop
Real people evaluate the performance.
Our team in Bloomington, Indiana reviews quality scores and call connectivity to find patterns and opportunities. Healthcare and other regulated industries expect human oversight of AI, and our team provides it.
Models refined. Insights show where translation models can be refined.
Coverage expanded. Insights show where language and dialect coverage can grow.
Changes shared in advance. Bloom schedules updates, tells customers about changes ahead of time, and publishes release notes.
Quality reviewLast 30 days
ESSpanish (Mexican)Average quality score96
VIVietnameseAverage quality score95
ARArabic (Lebanese)Average quality score94
Scores and performance data. No audio or transcripts.
Always private
Every conversation stays private.
Our team never listens to your calls or reads transcripts. They evaluate translation performance from quality scores and performance data alone.
Your conversations stay yours. Recordings and bilingual transcripts stay with the people you authorize.
Our team sees performance. Quality scores, call connectivity, and usage data.
Never used for training. Customer calls are never used to train models.
Records available depend on your plan and retention settings.
Who does what
Technology scores every call. People make it better.
Quality checks run automatically on every translation. Our team reviews the results and turns them into improvements.
The technologyAutomatic
Scores every translation.
Every translated utterance gets a quality score as the call happens. The score comes from an independent model, so translation never grades its own work.
A quality score for every utterance, accuracy measured word by word.
Scores only
The peopleBloomington, Indiana
Review the performance.
Our National Command Center team reviews the scores and call performance, then drives improvements. They never listen to your calls.
Review
Spot patterns
Improve
Performance data only. Your conversations stay private.
Human oversight of AI translation, built for regulated programs.
In healthcare, language access is a compliance issue for every health plan. The National Command Center brings people into the loop and keeps every conversation private.
Every call
Scored for translation qualityUtterance by utterance, by an independent model
Word level
Accuracy scoringEvery word translated, with no paraphrasing
0
Calls our team listens toQuality scores and performance data only
Meet the team behind quality. Book a demo and see TranslateOS on a live call.
No. The National Command Center monitors translation quality scores and performance data. It does not listen to customer conversations or see transcripts. Recordings and transcripts stay with your authorized users.
Who owns our data?
You do. Your data is your data. Every recording, transcript, and record from your calls is owned by you, the customer. We never use your data to train our models.
What is the National Command Center?
The National Command Center is the TranslateOS human-in-the-loop quality team, based in Bloomington, Indiana. Built for regulated industries, it is the first of its kind. The team reviews translation quality scores and performance on every call, spots issues, and drives ongoing improvements. It is included with every plan.
How is translation quality scored?
TranslateOS keeps translation and quality scoring separate. One model translates. A second, independent model scores each translated utterance, so the translation model never grades its own output. Accuracy is scored at the word level.